
Table of Contents
- Start With the Question That Actually Matters
- What You're Actually Getting Access To
- Decoding the Parameter Count Before It Misleads You
- Where It Actually Lands on Independent Benchmarks
- The Cost Math, Worked Through Properly
- The One Number That Should Change How You Use It
- A Licensing Promise, Not Yet a Licensing Fact
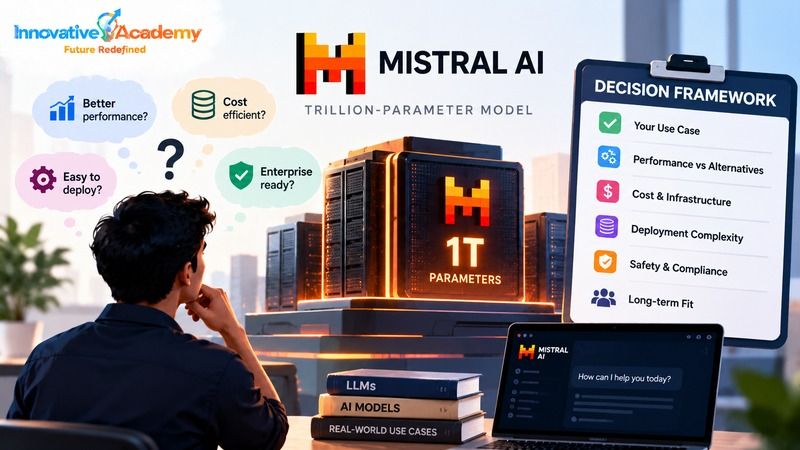
- Three Questions to Actually Ask Before Picking This Model
- Turning a Model Release Into Something You Can Build at Innovative Academy
- FAQs
- Final Thoughts
1. Start With the Question That Actually Matters
Every new model release gets covered the same way: a headline number, a wave of excitement or skepticism, and not much help actually deciding whether to use the thing. Mistral Large 4 went into public preview on October 6, 2026, carrying the kind of headline number, 1.05 trillion parameters, built for exactly that cycle. The question worth actually answering isn't "Is the model impressive?" It's "Should I build with this specific model for this specific task?" That question has a real, specific answer once you work through what the model does well and where it struggles.
2. What You're Actually Getting Access To
Right now, access means Mistral's hosted API, model ID mistral-large-4, accepting text and images, and offering a toggle, reasoning_effort, that switches it between a faster instruct mode and a slower reasoning mode. It comes with the infrastructure a production application actually needs rather than just a chat window: function calling, structured output formats, document-grounded question answering, request batching, and a built-in Agents API with tool integration.
Mistral's own documentation lists a 1 million token context window; independent testing from Artificial Analysis puts the real figure closer to 524,000. That gap between the two numbers hasn't been explained or resolved publicly as of this writing, which is itself worth factoring into any capacity planning.
3. Decoding the Parameter Count Before It Misleads You
Here's what the 1.05 trillion number doesn't tell you on its own: Mistral Large 4 never actually runs all 1.05 trillion parameters at once for any single request. It's a mixture-of-experts design, which means a routing mechanism picks a much smaller working subset. Mistral's own sources put it somewhere between 49 and 52 billion parameters to handle any given token, while the rest of the model's capacity sits available but unused for that specific request. That's the entire point of the architecture: it lets the model hold a genuinely enormous amount of specialized knowledge in reserve without paying the full computational cost of a dense model that large on every single query.
4. Where It Actually Lands on Independent Benchmarks
On Artificial Analysis's Intelligence Index, an aggregate score pulling from many different task types, Large 4 posts a 38.4. That sounds abstract until you see it against Large 3's 9.3, a genuinely enormous jump from release to release.
Set against its actual current competition, though, the picture is more middle-of-the-pack: Qwen 3.8 Max comes in at 45.4 and Kimi K3 at 43.6, both ahead of it, while DeepSeek's V4.1 Flash edges it out at 39.5. Mistral itself doesn't claim a general crown here. The model's strongest showings, per the company's benchmarking, come in narrower lanes: cyber-defense-style tasks, legal-agent workflows, and reading documents and charts. That's a meaningfully different and more honest claim than "best available."
5. The Cost Math, Worked Through Properly
This is where the model's case actually gets interesting rather than merely competitive. Launch pricing sits at $0.68 per million input tokens and $2.09 per million output tokens, roughly half of list pricing ($1.36 / $4.18), with batched requests running another 50% below whichever rate applies and no stated expiration on the discount.
Artificial Analysis's standardized cost-per-task metric puts Large 4 at about $1.13 per task at list price, dropping to roughly $0.57 at the sale rate. That beats Qwen 3.8 Max's $5.41 by a wide margin despite Qwen's higher raw intelligence score, while still landing above DeepSeek V4.1 Flash's $0.27.
Translate that into a decision rule: if your use case tolerates a slightly lower ceiling on raw capability in exchange for a meaningfully lower bill, the math genuinely favors Large 4 over several higher-scoring alternatives.
6. The One Number That Should Change How You Use It
Buried further down the benchmark sheet is the number that should actually shape how anyone deploys this model: a 41.9% hallucination rate on Artificial Analysis's test of pure factual recall. That's the kind of test that checks whether a model confidently states something false when answering purely from its training rather than from information it's been handed.
Practically, that means Large 4 is a poor choice for any application that asks it to answer open-ended factual questions from memory alone, and a considerably better one for applications that hand it source documents to reason over: retrieval-augmented setups, document Q&A, or anything where the model's job is interpreting supplied material rather than recalling facts unaided.
7. A Licensing Promise, Not Yet a Licensing Fact
"Open-weight" is the term Mistral is using for Large 4, but as of this writing, it describes an intention, not a current reality. There's no Hugging Face repository yet, and no license has actually been named for whatever eventually gets released, with Mistral committing only to a by-end-of-October-2026 timeline.
There's real precedent for Mistral following through generously: Large 3 shipped under the fully permissive Apache 2.0 license, and the smaller Medium 3.5 uses a modified MIT license. But anyone whose project specifically requires self-hosted, license-cleared weights today, not at the end of the month, needs to treat that distinction as more than fine print.
8. Three Questions to Actually Ask Before Picking This Model
Before reaching for Large 4 on a real project, three questions do most of the useful filtering:
- Does the task need the model to recall facts unaided, or can it be designed around retrieval and supplied context instead, given the hallucination rate above?
- Does the cost advantage actually matter at your expected request volume, or is the benchmark gap to higher-scoring alternatives like Qwen 3.8 Max or Kimi K3 more important than the price gap for this specific use case?
- Can the project wait on the open-weights promise if self-hosting matters, or does it need something license-confirmed today?
Answering those honestly does more for a real decision than any single benchmark number could.
9. Turning a Model Release Into Something You Can Build at Innovative Academy
Innovative Academy's Python program in Bangalore is where the three questions above stop being abstract and become code: writing the API calls, handling the structured outputs, wiring up function calling, and the actual mechanics that separate reading about a model release from shipping something that uses it.
10. FAQs
1. Can I self-host Mistral Large 4 today?
No. It's currently available only through Mistral's hosted API. Open weights are promised by the end of October 2026, with no license named yet.
2. Is it the smartest open model available right now?
No, not by independent measurement. Artificial Analysis scores it below both Qwen 3.8 Max and Kimi K3, and roughly in line with DeepSeek V4.1 Flash. Its specific advantages are price and a few narrower task categories, not an overall intelligence lead.
3. Does the trillion-parameter figure mean it's proportionally slower or costlier to run?
No. As a mixture-of-experts model, only about 49 to 52 billion of those parameters activate for any given token, which is what keeps a model this large practically usable.
4. Should I trust its answers to general knowledge questions?
Not without supplying it with source material to work from. Its 41.9% hallucination rate on pure recall testing means it's considerably more reliable when grounded in retrieved or provided documents than when relying on its training alone.
5. What's the realistic reason to pick it over a higher-scoring competitor?
Mostly cost efficiency at scale. Its price-per-task comes in well below several higher-benchmarking rivals, which matters most for high-volume or cost-sensitive applications where the absolute top intelligence score isn't the deciding factor.
11. Final Thoughts
The useful way to think about Mistral Large 4 isn't as a leaderboard entry (it doesn't top the leaderboard) but as a specific, honest trade: solid general capability, a real price advantage over several better-scoring rivals, and a couple of genuine specialty strengths, in exchange for a meaningfully higher hallucination rate on unaided recall and an open-weights promise that hasn't actually arrived yet. Making that trade deliberately, rather than reacting to the trillion-parameter headline, is the actual skill worth building before adopting any model, this one or whichever one replaces it next quarter.
Innovative Academy — Contact for course details: 8447712333
Sources:
- AI — Mistral Large 4: Specs, Pricing, Benchmarks, and Who Should Use It
- Innovative Academy — Python Training in Bangalore