
A Global Microsoft 365 Outage Took Down Outlook, Teams, and Copilot for Nearly a Day — Here's the Part Microsoft Has Actually Verified
Table of Contents
- What happened, and when
- A detail worth flagging: two sources, two different start times
- What Microsoft has said about the cause — and what it hasn't
- What Microsoft explicitly ruled out
- How long it actually took, and the apology
- Why this incident is a genuinely good Azure lesson
- What we're not claiming
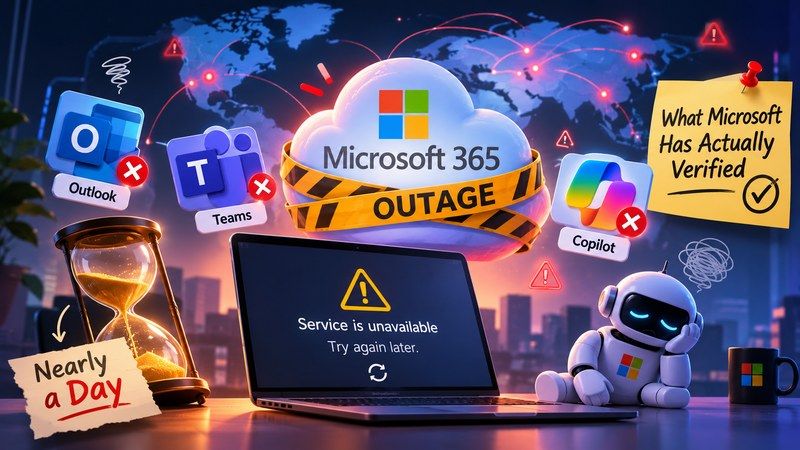
A single cloud provider going down for a day is the kind of event that reminds a lot of people, all at once, how much of their work actually depends on someone else's infrastructure. On November 12, 2026, that provider was Microsoft, and the list of things that stopped working cleanly — Outlook, Teams, SharePoint, Copilot — is long enough that this is worth picking apart carefully rather than repeating whichever headline summary is shortest.
What happened, and when
Microsoft 365 users began reporting problems on Thursday, November 12, 2026. Per Microsoft's own admin center notice (tracked internally as MO1550821), the affected services included Exchange Online, Microsoft Teams, SharePoint Online, Microsoft 365 Copilot, and Microsoft Defender XDR. Downdetector's complaint tracker showed the scale quickly: Security Affairs, reporting the same day, recorded more than 97,000 Outlook-specific incident reports logged by 2:07 p.m. ET. Al Jazeera's reporting the following day put the geographic spread at 74 countries and territories within roughly the first hour, with a later tally — around 07:00 GMT on Friday — still showing more than 43,000 Outlook problem reports across 72 countries. Notably, the disruption wasn't confined to Microsoft's own products: Reuters reported, and Security Affairs relayed, that OpenAI's and Anthropic's own connectors into Microsoft 365 were also affected, with OpenAI telling users that "new connections might fail and tools might not work properly."
A detail worth flagging: two sources, two different start times
Here's a genuine discrepancy worth being upfront about rather than quietly picking one number: Security Affairs reports that Microsoft stated the outage began at 1:26 p.m. ET. Al Jazeera, however, reports the disruption starting around 16:00 GMT on Thursday — which converts to roughly 11:00 a.m. ET, over two hours earlier. Neither outlet appears to be wrong on its own terms; they may be describing different stages of the same unfolding incident (an earlier, smaller disruption that widened later), or one of the two times may simply be inaccurate. Either way, this piece isn't resolving that gap by picking whichever number sounds more precise — if the exact start time matters for your own purposes, check Microsoft's service health history directly rather than relying on either secondhand figure.
What Microsoft has said about the cause — and what it hasn't
Microsoft's explanation evolved over the course of the incident, which is itself informative. Early on, the company's public messaging attributed the disruption to elevated load. It then revised that framing directly: in a post on X quoted by Security Affairs, Microsoft stated, "We determined the elevated load isn't driven by an increase in traffic, but by a number of servers being unexpectedly unavailable." Later admin-center language, quoted by Windows Latest, went a step further: "The incident was introduced by an issue during an earlier network capacity upgrade that surfaced following a recent network change." That's a real technical claim — a capacity upgrade created a condition that a subsequent network change then triggered — but it's not a complete postmortem. As of the sources reviewed for this piece, Microsoft had not published the full post-incident report, stating instead, "We will provide a full post-incident report once our review is complete." Al Jazeera's reporting the same week says plainly that "Microsoft has not published a root cause" at the time of its writing. Until that full report lands, the network-capacity-upgrade explanation should be read as Microsoft's working account, not the final engineering write-up.
What Microsoft explicitly ruled out
Two things Microsoft was specific about denying, even while the full cause remained unpublished. On the question of a cyberattack, Charles Lamanna, Microsoft's EVP of Copilot, Agents, and Platform, posted on X that "there is no indication this is the result of malicious or cyber activity." On the question of AI involvement specifically — a reasonable thing to wonder about, given Copilot was one of the affected services — Microsoft's own statement, quoted by Windows Latest, was direct: "This was a technical issue not related to cyber or AI / agents." Both denials are worth taking at face value as Microsoft's stated position, while keeping in mind that neither is independently verified by a third party in the sources reviewed here — they're Microsoft describing what the problem wasn't, ahead of describing, in full, what it was.
How long it actually took, and the apology
Windows Latest reports that "after almost 20 hours, Microsoft confirmed that most of its servers were back online," while its own intro describes the overall disruption as running "more than a day" once slower regional recovery is counted. Microsoft's own language, also quoted by Windows Latest, described restoration as happening gradually, "validating stability at each stage" rather than flipping back on all at once — which is consistent with an incident where recovery dragged on past the point most users would call it "over." Microsoft also issued a direct apology: "We are deeply sorry for the disruption this incident has caused our customers and partners."
Why this incident is a genuinely good Azure lesson
Setting aside the specific headline services, the mechanics of this incident are a genuinely useful case study for anyone building Azure skills: a maintenance-related change to network capacity, interacting with a separate network change, ended up taking down services that look, from the outside, like they have nothing to do with networking at all — email, chat, document collaboration. That gap between "the thing that broke" and "the things that visibly stopped working" is exactly why network design, redundancy, and change-management discipline are core parts of cloud administration rather than a narrow specialty. That connective layer — the networking and infrastructure fundamentals underneath the services that get all the attention — is exactly what Innovative Academy's Azure course in Bangalore spends real time on, precisely because an incident like this one is a reminder that outages rarely stay contained to the layer where the actual mistake happened. Contact for course details: 8447712333.
What we're not claiming
We're not resolving the roughly two-hour gap between Security Affairs' reported 1:26 p.m. ET start time and Al Jazeera's reported ~11:00 a.m. ET (16:00 GMT) start time — both are attributed to credible reporting on the same incident, and this piece isn't guessing which is more accurate. We're not treating "an issue during an earlier network capacity upgrade" as Microsoft's final, complete technical explanation — Microsoft itself has said a full post-incident report is still pending as of the sources checked here, and Al Jazeera's own reporting states that no root cause had been published at the time of its writing. We're not independently confirming the "not cyber, not AI" denials beyond repeating them as Microsoft's and Charles Lamanna's own stated positions — they're company statements made during an active incident, not findings from an independent audit. And we're not asserting a precise total user count affected; Al Jazeera's reporting notes directly that "Microsoft has not confirmed the number of users who have been affected," so the Downdetector figures cited here describe reported complaints, not a confirmed customer count.